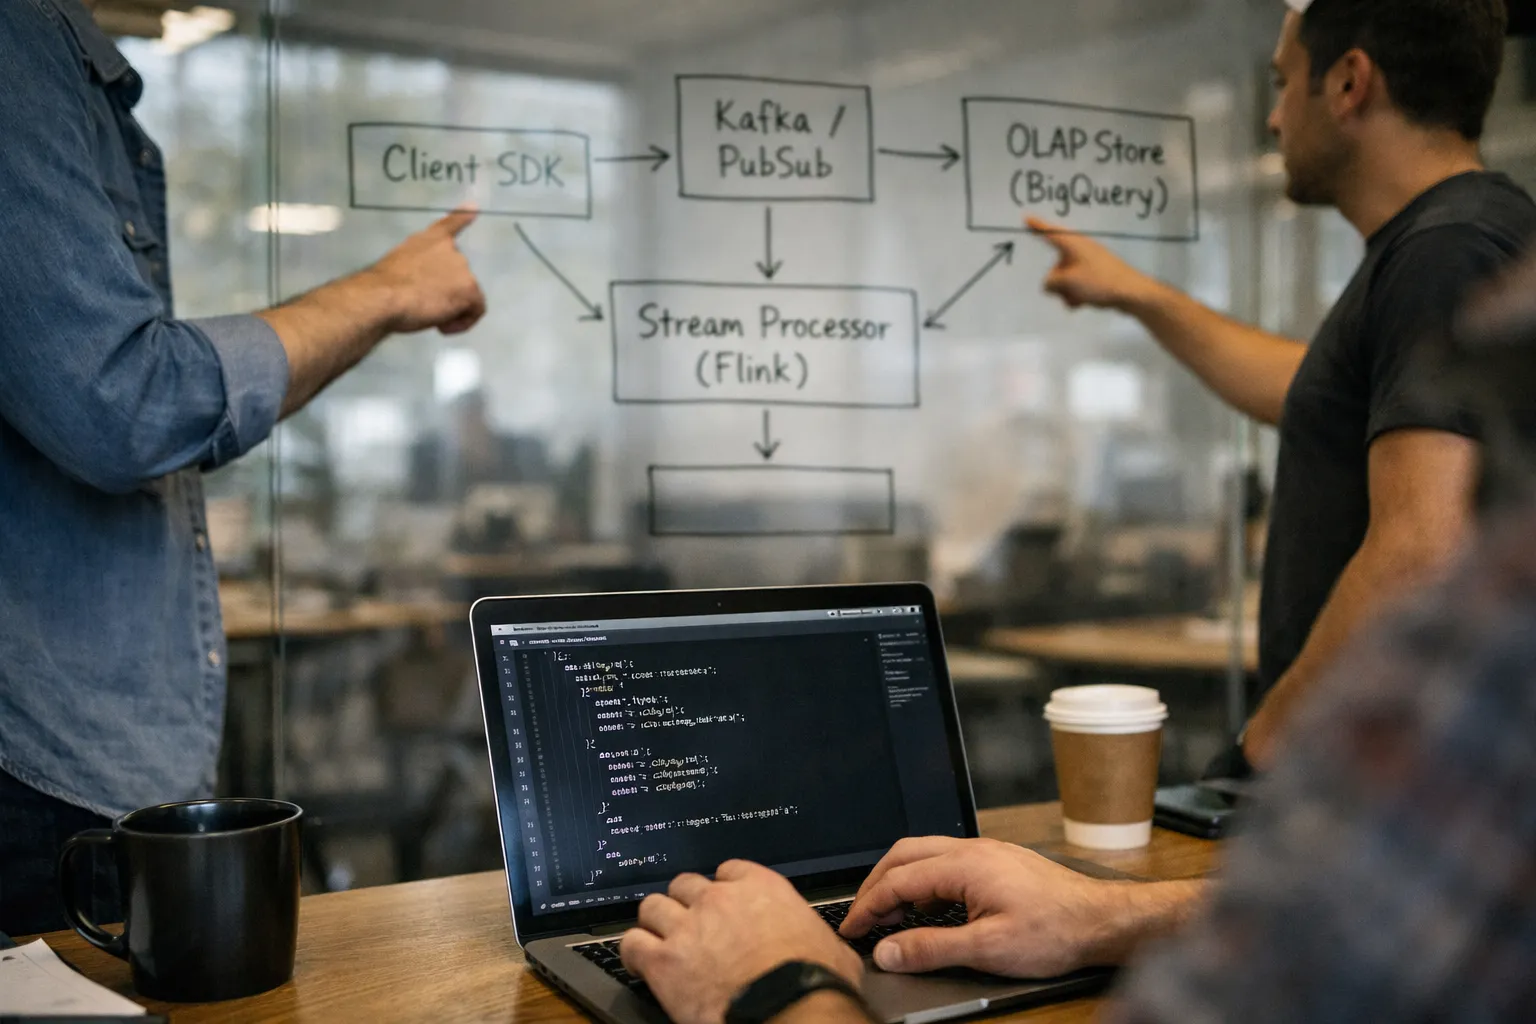
Usage-based monetization continues to drive adoption and revenue growth for B2B SaaS vendors in 2026. But turning raw product activity into accurate, auditable invoices is one of the hardest engineering problems for product and finance teams. This guide walks a product- and engineering-focused audience through a practical, event-driven implementation: defining meterable units, instrumenting events, ingest patterns, aggregation, reconciliation, billing integration, monitoring, and migration steps.
Why an event-driven approach?
An event-driven metering pipeline captures product usage as immutable events (e.g., "job.ran", "api.call", "seat.assigned") and processes them asynchronously into billable records. Benefits:
- Durability and auditability: raw events are retained for reconciliation and disputes.
- Scalability: decouples product instrumentation from billing systems via buffers/streams.
- Flexibility: supports multiple aggregation windows (minute, hour, day, monthly) and pricing models without changing source instrumentation.
- Near-real-time metering: enables consumption dashboards and quota enforcement.
Core components of the pipeline
- Instrumented product events (client/server SDKs, backend hooks)
- Event ingestion (Pub/Sub / Kafka / EventBridge / Kinesis)
- Stream processing/enrichment (Kafka Streams, Flink, AWS Lambda, Dataflow)
- Aggregated metrics store (time-series or OLAP: ClickHouse, BigQuery, Snowflake)
- Billing engine integration (Stripe Usage Records, Zuora, Chargebee, custom)
- Audit log and raw event storage (object store: S3/GS/ADLS, or cold tables)
- Reconciliation, dispute handling, and exports to finance
Step 1 — Define meterable units and schemas
Before any code, align product, finance, and legal on what counts as usage. Common dimensions:
- Meter ID: canonical product feature or resource (e.g., "encoding.seconds", "api.requests")
- Quantity: numeric amount (integer or fractional)
- Timestamp: event occurrence time in UTC
- Tenant identifiers: customer_id, subscription_id, account_region
- Context: resource_id, plan_id, region, pipeline_version
Example canonical event schema (JSON):
{
  "event_id": "uuid-v4",
  "tenant_id": "acct_123",
  "subscription_id": "sub_987",
  "meter_id": "api.requests.v1",
  "quantity": 1,
  "timestamp": "2026-09-25T14:32:01Z",
  "resource_id": "request_abc",
  "metadata": {"endpoint":"/v1/search","region":"eu-west-1"}
}
Principles when defining meters
- Make meters stable and versioned — avoid changing a meter's semantics after billing starts. If semantics change, create a new meter_id (e.g., "api.requests.v2").
- Avoid ambiguity — document whether quantity is cumulative, delta, or gauge.
- Keep meter granularity sensible — too fine-grained leads to high event volume and complex pricing rules.
Step 2 — Instrument events reliably
Instrumentation should be lightweight and idempotent. Two proven patterns:
- Emit events from the server-side gateway or backend service (recommended for accuracy).
- Client-side counters for ephemeral or offline usage, with periodic flush and de-duplication tokens.
Best practices:
- Include an event_id to support deduplication.
- Capture both occurrence time and ingestion time.
- Batch small events; avoid synchronous writes to billing endpoints to keep latency low.
Step 3 — Choose ingestion and buffering
High-level decision: streaming (real-time) vs. micro-batch (periodic). Consider SLA and volume:
- Real-time: use Kafka, Confluent Cloud, AWS Kinesis, or GCP Pub/Sub + stream processors when you need near-instant quota enforcement and dashboards.
- Micro-batch: use batched ingestion into object storage and process daily for low-volume or cost-sensitive use cases.
Design the ingestion to guarantee at-least-once delivery and support idempotency in downstream aggregation.
Step 4 — Enrich and aggregate
Stream processors enrich events with subscription and plan details (price per unit, free tiers, discounts) by joining on a compact, frequently-updated "subscription cache". Approaches:
- Stateful stream processing (Flink, Kafka Streams): maintains a local view of active subscriptions for fast joins.
- Stateless processors: call a subscription service (careful of latency) or pre-enrich at ingestion time.
Aggregation windows depend on pricing model:
- Per-minute/second for quotas and rate-limiting
- Hourly/daily for internal dashboards
- Monthly for final billing records
Sample SQL to compute daily totals in an OLAP store:
SELECT tenant_id, meter_id,
       DATE_TRUNC('day', timestamp) as day,
       SUM(quantity) as total_quantity
FROM raw_usage_events
WHERE timestamp >= '2026-09-01'
GROUP BY tenant_id, meter_id, day;
Step 5 — Produce billable usage records
Billing systems typically expect one canonical usage record per subscription per pricing unit for a billing period. Two patterns:
- Push aggregated usage to billing APIs (e.g., Stripe Usage Records API) at fixed cadence.
- Generate provisional invoice items in a billing database and finalize at invoice time (common when using Zuora or enterprise billing).
Key considerations:
- Idempotency: tag records with invoice_period_start/ end and an idempotency key.
- Proration and plan changes: if a subscription changes mid-period, compute prorated usage attribution before you push to billing.
- Currency and taxes: ensure prices are applied in the correct currency and include taxable flags for tax engines.
Step 6 — Reconciliation and dispute workflow
Reconciliation is where finance and engineering meet. Implement at least two reconciliations:
- Daily technical reconciliation: compare stream-aggregated charges to usage in the billing database; flag mismatches over a threshold.
- Monthly financial reconciliation: verify total invoiced amounts against aggregated usage totals and expected revenue recognized.
Build a dispute flow:
- Expose raw events and aggregated summaries to customer support via a secure UI.
- Support creation of credit memos and manual adjustments with full audit trails.
- Keep a retention policy for raw events (e.g., 2 years) to handle later disputes and audits.
Step 7 — Monitoring, SLOs, and cost control
Monitor both correctness and operational cost:
- Correctness metrics: percent of usage events reconciled, unprocessed events backlog, late-arriving events rate.
- SLAs: e.g., 99% of events processed and visible in dashboards within 5 minutes; 100% of billing records generated within 24 hours of period end.
- Cost metrics: storage costs for raw events, streaming costs (ingress, egress), and billing API call volume.
Optimization levers:
- Downsample or aggregate very high-volume non-billable telemetry before long-term storage.
- Use columnar OLAP for monthly aggregation (BigQuery/Snowflake/ClickHouse) instead of expensive row-by-row databases.
- Tier retention: hot data (90 days) in low-latency store; archived cold data in object storage.
Step 8 — Integrations and vendor choices
Common integrations as of 2026:
- Payment & billing: Stripe (Usage Records API), Chargebee, Zuora — choose based on enterprise features like revenue recognition.
- Streaming: Kafka/ Confluent for high throughput, or managed Pub/Sub/Kinesis for simpler ops.
- Analytics: BigQuery or Snowflake for large-scale aggregation; ClickHouse for low-latency dashboards.
- Tax & Compliance: TaxJar, Avalara; ensure the billing engine supports tax metadata.
Design your system to make the billing engine pluggable. Keep a canonical billable payload mapping layer so you can change providers without re-instrumenting the product.
Step 9 — Testing and validation
Test at three levels:
- Unit tests for instrumentation libraries (idempotency, event schema).
- Integration tests with a synthetic tenant behavior across expected and edge cases (plan changes, refunds, retroactive credits).
- End-to-end smoke tests in staging that generate usage, push through the pipeline, and produce draft invoices.
Run "chaos" tests: simulate duplicate events, dropped messages, and late-arriving events to validate reconciliation rules.
Step 10 — Migration checklist (from legacy or manual billing)
- Map existing invoice line items to canonical meter_ids.
- Instrument a shadow path that writes both legacy billing records and new events concurrently for 1-2 billing cycles.
- Run reconciliation reports: any >1% discrepancy requires rollback or rework.
- Communicate to select pilot customers and offer clear dispute/support channels.
- After pilot, gradually increase rollout with contingency for manual credits.
Common pitfalls and how to avoid them
- Ambiguous meters — document and version meters; never change semantics silently.
- Late events causing billing under/overcharges — implement cutoffs, late-arrival policies, and clear communication about adjustment windows.
- No audit trail — retain raw events and store immutable usage snapshots at invoice generation time.
- Coupling ingestion to billing latency — decouple with durable streams and process asynchronously.
- Underestimating costs — model the storage and processing cost of raw events per 1M events to choose sensible retention.
Checklist: Minimum viable metering system
- Documented meter catalog with stable IDs and semantics
- Instrumented, idempotent events with event_id and UTC timestamps
- Durable ingestion (managed streaming or object storage) with retention policy
- Aggregation layer that enriches with subscription/plan data
- Push mechanism to billing engine with idempotency and proration handling
- Daily reconciliation job and dispute UI for support
- Monitoring for correctness, latency, and cost
Final notes — organizational and legal
Metering and billing is as much organizational as technical. Bring finance, legal, support, and engineering into every stage: meter definitions, dispute SLAs, and customer-facing dashboards. Ensure terms of service and contracts reflect how usage is measured, rounding rules, and adjustment windows to reduce disputes.
When implemented correctly, an event-driven metering pipeline converts product telemetry into predictable revenue while giving customers transparent, auditable invoices. The engineering investment pays back through fewer disputes, faster price experimentation, and the ability to scale usage-based plans across thousands of customers.